
Find wider minima
Applying noise
Dropout can be interpreted as applying multiplicative Bernoulli noise to the network activations.
This leads to the idea of applying noise to other parts of the network during training to make the final model more robust.
One option is to add noise to the input data; this smooths out the learned function.
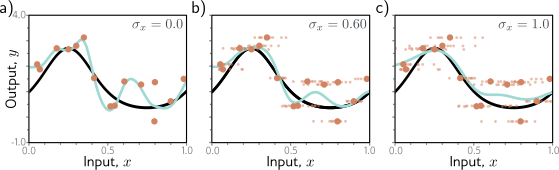
For regression problems, it can be shown to be equivalent to adding a regularizing term that penalizes the derivatives of the network’s output with respect to its input.
An extreme variant is adversarial training, in which the optimization algorithm actively searches for small perturbations of the input that cause large changes to the output.
These can be thought of as worst-case additive noise vectors.
A second possibility is to add noise to the weights.
This encourages the network to make sensible predictions even for small perturbations of the weights.
The result is that the training converges to local minima in the middle of wide, flat regions, where changing the individual weights does not matter much.
Finally, we can perturb the labels.
The maximum-likelihood criterion for multiclass classification aims to predict the correct class with absolute certainty.
To this end, the final network activations (i.e., before the softmax function) are pushed to very large values for the correct class and very small values for the wrong classes.
We could discourage this overconfident behavior by assuming that a proportion \(ρ\) of the training labels are incorrect and belong with equal probability to the other classes.
This could be done by randomly changing the labels at each training iteration.
However, the same end can be achieved by changing the loss function to minimize the crossentropy between the predicted distribution and a distribution where the true label has probability \(1−ρ\), and the other classes have equal probability.
This is known as label smoothing and improves generalization in diverse scenarios.